Part 2 of 5 · AI LLM Engineering
Building a Conventional Commit Generator with a Local LLM
I give the local Qwen 3 model one real job: read my staged git diff and write the Conventional Commit message. No training yet, just prompt engineering, three worked examples, and 14 fixed diffs to score against. The score goes 9 out of 14, then 11, then stops.

Charith 'Alex' Gunasekara
Head of Development & Engineering
In Part 1 I got a language model running on my Mac with Apple MLX. Offline, about 30 tokens a second, no API key and no bill. That is a good start, but a model that can answer anything is not yet useful. It needs a job.
So in Part 2 I give it one: read my staged changes and write the commit message.
I picked this job because it is small and easy to check. Either the message is correct or it is not. I cannot hide behind a nice demo.
There is no training in this part. Everything here is prompt engineering, which just means what I say to the model and how I say it. I wanted to see how far that takes me before spending days on a dataset. If a good prompt was enough, there would be no point writing the rest of this series.
It is not enough. But finding the exact point where it stops was the most useful thing I did.
What a Conventional Commit is
Conventional Commits is a simple agreement about how a commit subject line should look:
type(scope): summary
For example, feat(login): disable sign in until fields filled. The type comes from a fixed list: feat, fix, perf, refactor, docs, style, test, build, ci, chore, revert. The scope is optional and says which area you changed. The summary is one short line. Lowercase, no full stop, and written as a command ("add", not "added").
The point is not to look tidy. The point is that a script can read your history. Release notes, version numbers and changelogs can then be generated for you. The cost is that someone has to write in this format every single time. By the fortieth commit of the day, that someone gets lazy. This is exactly the kind of small, repeated, private job I want to give to a local model.
Measure first, or you are only guessing
My first idea was to write a better prompt straight away. I am glad I did not, because I would not have known if it helped.
Before touching the prompt I built a fixed test set: 14 diffs in a samples/ folder. Each one is a realistic change. I spread them across the stacks I actually work with and across commit types.
01-swift-feat-login-disable.diff      08-react-fix-useeffect-deps.diff
02-swift-fix-force-unwrap.diff        09-node-perf-cache.diff
03-python-feat-endpoint.diff          10-docs-readme.diff
04-python-fix-empty-input.diff        11-chore-bump-deps.diff
05-springboot-feat-controller.diff    12-test-add-unit.diff
06-springboot-refactor-service.diff   13-kotlin-fix-lifecycle-collect.diff
07-react-feat-component.diff          14-dotnet-feat-pagination.diff
Then I wrote a script that runs all 14 through the model and saves the results to a markdown file with the date on it. Same questions, same order, every time. When I change the prompt I run it again and I can see what improved, what stayed the same, and what broke.
I follow two rules with this set for the rest of the series.
I never train on it. In Part 4 I will fine-tune the model using a separate dataset. If any of these 14 diffs were in that training data, the model would already know the answers and the score would mean nothing.
I never overwrite old results. Every run gets its own file. I learned this the hard way. One careless re-run wrote over my first saved baseline, and that folder has no version history, so it was gone. The script now refuses to write over a file that already exists unless I force it. It checks this before loading the model, not after a three minute run.
If you cannot say what the score was before your change, you are not improving anything. You are only moving the problem around.
Reading the change
The input is whatever is staged right now.
def get_staged_diff() -> str:
    result = subprocess.run(
        ["git", "diff", "--staged", "--no-color"],
        capture_output=True,
        text=True,
    )

    if result.returncode != 0:
        detail = result.stderr.strip() or "git diff failed."
        raise RuntimeError(f"Could not read the staged diff: {detail}")

    diff = result.stdout.strip()

    if not diff:
        raise ValueError(
            "Nothing is staged. Stage your changes first with `git add`."
        )

    return diff
Two small details. The git command is a list of arguments, not one long string given to a shell, so nothing inside it can be re-read as a shell command. And I use --staged on purpose. I want the exact changes that a git commit would record right now, not the half-finished work sitting in my working folder.
The empty check is not just extra safety. Without it the model gets an empty diff, and a model that is asked to describe nothing will happily make something up.
First try: tell it the rules
My starting prompt was reasonable but vague. It listed some types "such as feat, fix, chore" and asked for something "concise". Here is what the model did with that freedom:
01-swift-feat-login-disable.diff
  ui(login): update welcome text and button label with disabled state

11-chore-bump-deps.diff
  deps(vite,react): update to latest versions 18.3.1 and 5.4.0
ui and deps are not Conventional Commit types. The model made them up. They are sensible guesses, and that is the problem. A model does not see any difference between "here are some example types" and "here is the full list of types". When I wrote "such as", I gave it permission to invent.
So I rewrote the prompt with three changes:
- A closed list. "Choose the type from THIS LIST ONLY. Never invent a type."
- A one line definition for each type. Listing the names alone tells the model nothing about when to use them.
- Simple rules for the mistakes I could see. Adding a check to stop a crash is
fix, notfeat. Making existing code faster isperf, notfeat.
I also asked for a clear format: lowercase, no full stop at the end, around 50 characters, and a lowercase scope.
Here is the whole prompt after the rewrite:
SYSTEM_PROMPT = """
You are a senior software engineer. Read the git diff and reply with ONE
Conventional Commit message and nothing else.

Format:  type(scope): summary
- scope is optional, lowercase, the area changed (e.g. login, orders, deps).
- summary: imperative mood, lowercase, no trailing period, about 50 chars max.

Choose the type from THIS LIST ONLY. Never invent a type:
  feat     - adds a new capability or feature
  fix      - corrects wrong or broken behaviour (crashes, bugs, edge cases)
  perf     - makes existing behaviour faster, without changing what it does
  refactor - restructures code without changing behaviour or adding features
  docs     - documentation only
  style    - formatting or whitespace only, no behaviour change
  test     - adds or changes tests only
  build    - build system, packaging, or dependency changes
  ci       - CI/CD configuration only
  chore    - routine maintenance that fits nothing above
  revert   - reverts a previous commit

Rules of thumb:
- Guarding against a crash or wrong result is fix, not feat.
- Making existing behaviour faster is perf, not feat.

Return only the one-line message: no markdown, no backticks, no quotes,
no explanation.
""".strip()
It is not clever. It is just specific. Most of the work is done by the words "THIS LIST ONLY" and by giving each type a short definition.
That fixed the invented types. deps became build. It also fixed sample 04, which had been marked as a feature before.
Score: 9 out of 14.
It also broke sample 08. That one went from a correct fix to refactor. This was my first real sign that a prompt only pushes the model in a direction. It does not lock anything. You push here, and something moves over there.
Second try: show it instead of telling it
The mistakes that were left were all judgement calls. The rule "a guard is a fix" was written in the prompt. The model just did not apply it to a diff where the code clearly moved around.
Rules are abstract. Examples are concrete. So instead of explaining harder, I showed the model three solved diffs before asking the real question.
The useful part is that I can write the model's own replies myself:
[system]     the rules
[user]       Generate a commit message for this diff:  <go diff>
[assistant]  feat(cart): apply discount to order total     ← I wrote this
[user]       Generate a commit message for this diff:  <ruby diff>
[assistant]  fix(session): guard missing token before decode
[user]       Generate a commit message for this diff:  <rust diff>
[assistant]  perf(search): use a set for banned id lookup
[user]       Generate a commit message for this diff:  <the real one>
The model never wrote those three answers, and it cannot tell the difference. All it sees is a conversation where the assistant has already replied three times in a very clear style. Continuing a pattern like that is what these models are built to do.
The examples live in their own file as plain data, so the code that builds the prompt stays readable:
FEW_SHOT_EXAMPLES: list[tuple[str, str]] = [
    (GO_FEAT_DIFF,   "feat(cart): apply discount to order total"),
    (RUBY_FIX_DIFF,  "fix(session): guard missing token before decode"),
    (RUST_PERF_DIFF, "perf(search): use a set for banned id lookup"),
]
Then build_messages turns each pair into two turns and puts the real question last:
USER_TEMPLATE = "Generate a commit message for this diff:\n\n{git_diff}"


def build_messages(
    git_diff: str, use_few_shot: bool = True
) -> list[dict[str, str]]:
    messages = [{"role": "system", "content": SYSTEM_PROMPT}]

    if use_few_shot:
        for example_diff, example_message in FEW_SHOT_EXAMPLES:
            # The question we pretend to have asked...
            messages.append({
                "role": "user",
                "content": USER_TEMPLATE.format(git_diff=example_diff),
            })
            # ...and the answer we wish the model had given.
            messages.append({"role": "assistant", "content": example_message})

    # The real request always comes last, so it is freshest in the model's mind.
    messages.append({
        "role": "user",
        "content": USER_TEMPLATE.format(git_diff=git_diff),
    })

    return messages
USER_TEMPLATE sits in one place for a reason. The examples and the real question must be worded exactly the same way. The model is matching the shape of the conversation, so if the wording drifts even slightly, the pattern gets weaker and the examples do less work.
The use_few_shot flag is there so I can turn the examples off and run the same 14 diffs with the rules only. Without that switch I could not say how much the examples were actually worth.
Each example targets a failure I had measured. Here they are in full.
The Go one is for sample 01, where the model answered ui(login). That diff changed a colour and also disabled a button. The model looked at the colour and invented a type for it. So my example has the same trap. A comment is reworded, which is cosmetic, and a discount is applied to the total, which is real behaviour.
diff --git a/internal/checkout/cart.go b/internal/checkout/cart.go
@@ -8,7 +8,7 @@ type Cart struct {
 	Items    []Item
 	Discount float64
-	Label    string // shown above the total
+	Label    string // heading for the summary row
 }

@@ -18,5 +18,10 @@ func (c *Cart) Total() float64 {
 	for _, item := range c.Items {
 		total += item.Price * float64(item.Quantity)
 	}
-	return total
+
+	if c.Discount > 0 {
+		total = total * (1 - c.Discount)
+	}
+
+	return total
 }
Answer: feat(cart): apply discount to order total. The comment change is ignored. The behaviour decides the type.
The Ruby one is for samples 02, 08 and 13, where the model kept saying refactor for diffs that add a guard. I understand why it does that. The code visibly moves around, so it looks like restructuring. But the old code crashed when the header was missing and the new code does not, so behaviour changed.
diff --git a/app/services/session_service.rb b/app/services/session_service.rb
@@ -6,8 +6,12 @@ class SessionService
   def current_user(request)
-    token = request.headers["Authorization"].split(" ").last
-    payload = JWT.decode(token, secret).first
+    header = request.headers["Authorization"]
+    return nil if header.nil? || header.empty?
+
+    token = header.split(" ").last
+    payload = JWT.decode(token, secret).first
+
     User.find_by(id: payload["sub"])
   end
 end
Answer: fix(session): guard missing token before decode. This was the most common mistake in my results, so it gets the clearest example.
The Rust one is for sample 09, where the model called a caching change a feat. Nothing new became possible there. The same function returns the same answers, only faster. That is perf.
diff --git a/src/index/search.rs b/src/index/search.rs
@@ -1,9 +1,13 @@
+use std::collections::HashSet;
+
 pub fn filter_matches(docs: &[Doc], banned: &[String]) -> Vec<Doc> {
-    docs.iter()
-        .filter(|doc| !banned.contains(&doc.id))
-        .cloned()
-        .collect()
+    let banned: HashSet<&String> = banned.iter().collect();
+
+    docs.iter()
+        .filter(|doc| !banned.contains(&doc.id))
+        .cloned()
+        .collect()
 }
Answer: perf(search): use a set for banned id lookup. Searching a list for every document is slow. A set lookup is not. Same result, less work.
All three also use a lowercase scope, a short summary and no full stop. The format gets taught by showing it, not only by writing another rule.
I used Go, Ruby and Rust on purpose. My test set uses Swift, Python, Java, React, Node, Kotlin and .NET. If my examples used the same languages, the model would be copying from the test paper instead of thinking, and my score would go up for the wrong reason. This is the easiest way to fool yourself when you measure something.
Score: 11 out of 14. Invented types: zero.
Sample 02 went from refactor to fix, and it copied some of my wording on the way:
my example:   fix(session): guard missing token before decode
the model:    fix(profile): guard invalid avatar path before fetch
You can see the learning happen. Nothing was trained here. The weights are exactly the same file I downloaded. The model just read a conversation and carried on in the same style.
A rule tells the model what to do. An example shows it. When the two disagree, the example wins.
The three it still gets wrong
This part interested me the most, and it is the reason the rest of the series exists.
Sample 09 did not move at all. I gave the model a perf example, and it still called a caching change a feat. My example makes code faster with a set lookup. Sample 09 makes code faster with a cache. Different technique, so nothing carried over. The model learned "this exact shape is perf". It did not learn "avoiding repeated work is perf".
Think about what would have happened if my example had also used a cache. Sample 09 would have flipped, my score would have read 12 out of 14, and I would have learned nothing except that models can copy. Keeping the examples different is what stopped me fooling myself.
Sample 13 got worse. It moved from refactor to feat. Both are wrong, but feat is further from the truth. When I show three examples marked feat, fix and perf, the model starts pulling unfamiliar diffs towards those three types. So every fix has a cost somewhere else.
docs(README) survived everything. I have a written rule saying scopes are lowercase, plus three examples that all use lowercase scopes, and the model still writes README in capitals because that is the filename. It is a small failure and it will not move.
Making it repeatable
None of the numbers above mean anything unless the model gives the same answer every time.
At each step, the model gives a score to every word it could write next. Temperature decides what happens with those scores. In Part 1 the chat used 0.7, which means pick randomly but favour the high scores. The second or third choice wins sometimes, so the same question gives a slightly different answer. That is good for conversation.
For this tool I want 0.0. Always take the highest score, so the same diff always gives the same message.
GREEDY_SAMPLER = make_sampler(temp=0.0)The obvious reason is trust. A commit tool that answers differently each run is a tool you stop using. The second reason matters more here. Without this, every number in this article would be meaningless. Sample 02 changing from refactor to fix could be my example working, or it could be luck, and I would have no way to tell.
One honest note. When I went to set this, I found that mlx-lm already uses greedy decoding by default. Its generate loop falls back to argmax when you do not pass a sampler. So this line changed nothing. I set it anyway. A default is somebody else's decision and it can change in the next release. My results were repeatable by accident before. Now they are repeatable by choice.
Treat model output as untrusted input
This message goes straight into git commit -m. That changes how I look at it.
I ask for one plain line, and most of the time I get one. Most of the time is not a guarantee. Models sometimes wrap the answer in a code block, or quotes, or write Commit message: in front, or add a paragraph explaining themselves. Any of those gives me a broken commit.
def clean_commit_message(raw_output: str) -> str:
    text = raw_output.strip()

    # Drop code fence lines, keep what is inside.
    if "```" in text:
        kept = [l for l in text.splitlines() if not l.strip().startswith("```")]
        text = "\n".join(kept).strip()

    # Keep the first line with real content. The rest is the model
    # explaining itself.
    text = next((l.strip() for l in text.splitlines() if l.strip()), "")

    # "Commit message: feat(x): y" -> "feat(x): y"
    lowered = text.lower()
    for prefix in LABEL_PREFIXES:
        if lowered.startswith(prefix):
            text = text[len(prefix):].strip()
            break

    # Strip matching wrappers, repeatedly, because '"`feat: x`"' happens.
    while len(text) >= 2 and text[0] == text[-1] and text[0] in WRAPPING_CHARACTERS:
        text = text[1:-1].strip()

    return text.rstrip(".").strip()
Ten lines of simple string handling. You would never take text from a stranger and pipe it into a shell command. Model output deserves the same care. A good prompt reduces bad output. It never removes it. This stays true after fine-tuning as well. A trained model is more consistent, not perfect.
The tool
All the pieces above meet in one function. It builds the turns, lets the tokenizer format them the way Qwen expects, generates, and cleans the result before anyone sees it.
def generate_commit_message(
    model: Any,
    tokenizer: Any,
    git_diff: str,
    use_few_shot: bool = True,
) -> str:
    if not git_diff.strip():
        raise ValueError("The Git diff cannot be empty.")

    messages = build_messages(git_diff, use_few_shot=use_few_shot)

    prompt = tokenizer.apply_chat_template(
        messages,
        tokenize=False,
        add_generation_prompt=True,
    )

    response = generate(
        model=model,
        tokenizer=tokenizer,
        prompt=prompt,
        max_tokens=MAX_TOKENS,
        sampler=GREEDY_SAMPLER,
        verbose=False,
    )

    return clean_commit_message(response)
apply_chat_template is the part worth knowing about. My list of system, user and assistant turns is just Python dictionaries. The model does not read dictionaries. Every chat model has its own special tokens that mark where a turn starts and ends, and the tokenizer that came with the model knows that format. So I hand it my list and it gives back one long string in the exact shape Qwen was trained on. add_generation_prompt=True adds the opening marker for the assistant's reply, so the model knows it is its turn to write.
max_tokens is 60. A commit message is about 15 tokens. That leaves plenty of room and still stops a model that decides to explain itself at length.
Then scripts/commit.py wraps it in a command line tool. Three flags, using argparse from the standard library:
parser = argparse.ArgumentParser(
    description="Write a Conventional Commit message for your staged changes.",
)
parser.add_argument(
    "--diff",
    type=Path,
    help="Read the diff from this file instead of git (useful with samples/).",
)
parser.add_argument(
    "--commit",
    action="store_true",
    help="Offer to create the commit after showing you the message.",
)
parser.add_argument(
    "--zero-shot",
    action="store_true",
    help="Drop the few-shot examples and send the rules alone.",
)
args = parser.parse_args()
action="store_true" means the flag takes no value. If --commit is there, args.commit is True. If it is not, it is False. argparse also builds --help for me from these descriptions, which is free documentation.
--diff is how I test against the samples/ folder without staging anything. --zero-shot is the switch I used to produce the "rules only" numbers earlier in this article.
Then the body reads the change and runs it:
if args.diff:
    git_diff = read_diff_file(args.diff)
else:
    try:
        git_diff = get_staged_diff()
    except (RuntimeError, ValueError) as error:
        raise SystemExit(f"{Colours.RED}✗{Colours.RESET} {error}")

model, tokenizer = load_local_model()

message = generate_commit_message(
    model=model,
    tokenizer=tokenizer,
    git_diff=git_diff,
    use_few_shot=not args.zero_shot,
)
The try block matters more than it looks. get_staged_diff raises a clear sentence when nothing is staged. Without catching it, Python prints a stack trace, and a stack trace tells a user nothing useful. SystemExit prints the message and stops.
By default it only prints. That is on purpose. The commit is the one thing here that changes something on my machine, so it sits behind a flag and a question:
SUGGESTED COMMIT MESSAGE
------------------------------------------------
fix(auth): add null check for authorization header

Create this commit? [y/N]
def confirm(question: str) -> bool:
    try:
        answer = input(f"{question} [y/N] ").strip().lower()
    except (EOFError, KeyboardInterrupt):
        # Ctrl-C or a closed pipe is not consent.
        print()
        return False

    return answer in ("y", "yes")
Only a y continues. Enter means no. Ctrl-C means no. A closed pipe means no. In a yes or no question, the default should always be the answer that does nothing.
The script also reads the diff before it loads the model. If nothing is staged you find out straight away instead of waiting for a model to load. And --commit will not run together with --diff. Writing a message for a file on disk and then committing it into whatever repository you happen to be standing in is not something anyone wants.
The video at the top of this article is that flow on a real change. I added a swipe to delete action to a SwiftUI list. This is what it left behind:
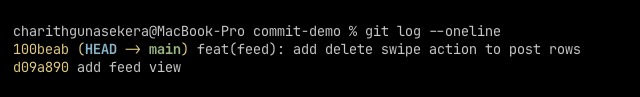
The message in the code block above, fix(auth): add null check for authorization header, is also real. It came from a small Python change the model had never seen, where I used .get() and returned early. It called it fix, not refactor. My Ruby example carried over to Python.
That makes sample 09 more interesting, not less. The lesson crossed a language boundary with no trouble, and did not cross a technique boundary at all. Few-shot examples generalise across surface details. They do not generalise across ideas.
Where prompting stops
Two rounds of work, and the honest scoreboard:
| Result | |
|---|---|
| Vague prompt | invented types, wrong types |
| Closed list, definitions, simple rules | 9 / 14 |
| Plus three worked examples | 11 / 14 |
Every improvement came with a small step backwards somewhere else. Fixing the type confusion pulled unfamiliar diffs towards the types I had demonstrated. The last three failures need the model to actually understand something. That caching is about speed. That adding a guard changes behaviour. There is no sentence I can add to a prompt that puts understanding in.
There is a second limit too, and it is quieter. Even when the model is right, it does not write like me. It writes like the average of everyone whose code it was trained on. add optional role prop and display is a perfectly fine commit message. It is not my commit message.
That is not a prompt problem. It is a weights problem. You cannot describe your own style well enough to write it down as a rule. You can only show it, many times, and let the model pick up the pattern.
That is what fine-tuning does.
Prompting moved the score. It never moved the understanding.
The code
The tool, the prompt, the 14 evaluation diffs and both "before" files are in one repository. Parts 3 and 4 add to the same one.
github.com/Charith1990/mlx-commit-lora
The model is not in there. scripts/download_model.py fetches it from Hugging Face on first run, the same way Part 1 did.
In Part 3 I build the training dataset. A few hundred real diffs, each paired with the commit message I would have written myself. Then in Part 4 I train a LoRA adapter on top of this same frozen Qwen, run the same 14 diffs through it, and put the two sets of results side by side.
The test set is ready. The "before" is saved and locked. Now I go and teach it.