Part 3 of 5 · AI LLM Engineering
Creating a Training Dataset for LoRA Fine-Tuning
How to build a fine-tuning dataset from nothing: 400 git diffs paired with commit messages, in the JSONL chat format mlx-lm reads. Where the messages come from, the terminal tool I built to review them, and why the checking script matters more than the training command.

Charith 'Alex' Gunasekara
Head of Development & Engineering
Part 2 ended at 11 out of 14. A closed list of types took the model to 9. Three worked examples took it to 11. After that, every fix I made broke something else, and the three failures that were left all needed the model to understand something rather than follow a rule.
There is no sentence you can add to a prompt that puts understanding in. The only other option is examples: a diff on the left, the right answer on the right, until the pattern sits in the weights instead of the prompt.
That is a training dataset, and it is the whole job. The training command in Part 4 is four lines and I will type it once. Everything the trained model becomes is decided here.
What one row looks like
mlx-lm reads JSONL. One JSON object per line, no commas between lines, no wrapping array. It accepts a few shapes, and I picked the chat shape because it matches how my tool already talks to the model:
{"messages": [
  {"role": "system",
   "content": "Write one Conventional Commit message for this git diff."},
  {"role": "user",
   "content": "Generate a commit message for this diff:\n\n<the diff>"},
  {"role": "assistant",
   "content": "feat(login): disable sign in until fields filled [CG]"}
]}
Two details in there cost me the most thought.
The system prompt is one line. Part 2's prompt is about 800 tokens of rules and worked examples. None of that is here. The rules stop being text I send every time and become part of the model: twenty tokens of instruction instead of eight hundred.
Whatever prompt is in the training data must be the prompt you send later. The model learns the shape of the conversation, not only the answer. Send a different one in Part 4 and nothing errors. The model just performs a bit worse than it should, and you go looking in the training settings.
One practical thing: the files must be called train.jsonl and valid.jsonl. The names are hardcoded in the library, and anything else gives an error about a missing dataset that never mentions filenames.
Where the messages come from
The plan said "a few hundred real diffs, each paired with the commit message I would have written myself". So I went looking for my own commits. Every git repository on my Mac, about 2,500 of them.
Roughly 65 of them are in Conventional Commit format.
The rest look like this:
Minor update.
Article added : SwiftUI navigation
Fixes
update
I cannot harvest a style out of my own history, because the style is not in my history.
Worse, most of those repositories are client work. It is not my code to feed into a model, and a model trained on it can repeat what it saw. That is a hard line rather than a licensing detail to sort out afterwards, and it removes about 90% of the code on my machine.
That left three options:
- Scrape open-source repositories. Then I am teaching the model the house style of strangers, and calling the result "my" model would be a lie.
- Write 400 messages by hand for changes I never made. Honest, but I would run out of imagination by the hundredth one.
- Put together 400 diffs myself, invented but realistic, reviewed one by one, each paired with the message I would write. No client code, nothing scraped, everything checkable.
I took the third one.
The dataset is not "data I collected". It is a set of decisions about what the model is allowed to learn from.
400 diffs, written and reviewed manually
They live in eight files of fifty. Each entry is small and complete:
{
    "id": "012",
    "stack": "kotlin",
    "type": "fix",
    "diff": """
diff --git a/app/src/main/java/com/example/sync/SyncService.kt ...
...
""",
}
Between 7 and 28 lines each, average 15. Realistic enough to be worth reading, small enough that the answer is not ambiguous.
The mix, by type and by stack:
feat 102   fix 94   test 53   refactor 47   perf 35
chore 24   docs 16   build 12   ci 10   style 7

swift 70   python 66   kotlin 52   node 50   react 47
springboot 46   dotnet 33   ci/docs/config 36
Two things in that list are deliberate.
The type field is my answer, not the model's. I set it as each diff was written, and the model never sees it. Ground truth has to be written down before you look at anyone's guess, or it is not ground truth, it is agreement.
Batch seven is deliberately unbalanced. After six batches, ci had three examples and build had two, and a type the model sees three times is a type it will never learn. So batch seven is nothing but the rare types. Write naturally and you get what you already write most often, which is not the same as balance.
Every diff is also distinct from the 14 evaluation diffs in samples/ and the three few-shot examples in Part 2. That separation is the only reason the Part 4 comparison means anything, so I check it at the end rather than trusting my memory.
The type I removed
There is no revert anywhere in this dataset, and there never will be.
A revert looks exactly like "delete this code". What makes it a revert is knowing the code was added in an earlier commit, and a diff does not carry that history. Real revert commits say Revert "..." only because git copies the subject of the commit being undone.
So training on reverts teaches the model to guess revert whenever it sees a lot of deleted lines. That is not a skill. That is a superstition.
I found this the practical way. One of my early diffs was written as a revert, and the model called it chore. Which is not wrong. It is simply unknowable from what it was given.
If the answer is not in the input, do not put it in the training data. You are not teaching a rule, you are teaching a guess.
Drafting 400 messages
Writing 400 commit messages by hand is a full day of typing, and by message 200 the quality drops whether you notice or not.
So I let the Part 2 tool write a first draft for each one, and planned to correct them. Few-shot on, temperature zero, one model load, about twenty minutes for all 400. The script writes each line to disk as soon as it is generated, so stopping it half way costs nothing.
I expected roughly 70%, based on a spot check of ten.
It scored 59%. 235 correct types out of 400.
The breakdown is more interesting than the number:
| Type | Correct | Total | |
|---|---|---|---|
| feat | 102 | 102 | 100% |
| docs | 16 | 16 | 100% |
| build | 9 | 12 | 75% |
| style | 5 | 7 | 71% |
| test | 35 | 53 | 66% |
| refactor | 19 | 47 | 40% |
| perf | 13 | 35 | 37% |
| fix | 33 | 94 | 35% |
| ci | 1 | 10 | 10% |
| chore | 2 | 24 | 8% |
A perfect score on feat. Not one miss in 102.
That looked like good news for about ten seconds. Then I counted what the model actually wrote across all 400 diffs:
the model wrote:   feat 211   fix 35   test 35   refactor 28   docs 28
                   build 23   perf 17   style 11   chore 10   ci 2

I had labelled:    feat 102   fix 94   test 53   refactor 47   perf 35
                   chore 24   docs 16   build 12   ci 10   style 7
It answered feat for more than half of every diff it was shown.
You cannot miss a feature if you call everything a feature. That 100% is not a skill, it is the shape of a model with one favourite answer. Here is where the other answers went:
I said fix       →  feat 36,  fix 33,  refactor 7,  and a tail
I said refactor  →  feat 25,  refactor 19
I said test      →  test 35,  feat 18
I said perf      →  feat 17,  perf 13
I said chore     →  docs 8,  build 7,  feat 7,  chore 2
I said ci        →  chore 4,  build 3,  feat 2,  ci 1
This is Part 2's ending, measured properly. With 14 diffs I could see that the model confused fix with feat and suspect a pattern. With 400 I can see that it barely has a concept of chore at all, and that everything it is unsure about falls towards feat.
A perfect score on one category is usually a bias, not an achievement. Check what the model answers across everything before you celebrate what it got right.
A tool for the part that cannot be automated
Now the review, where the drafts get corrected. This is the only step where my own judgement enters the dataset.
Editing JSON by hand is the wrong tool for 400 decisions. Your attention goes on commas and quotes, and one bad keystroke breaks a file with no version history behind it.
So I built a small terminal tool. It shows one diff with the draft underneath and waits. Enter accepts, typing replaces, e puts the draft on the input line so a one word fix is a one word fix. Each decision goes to disk as I make it and is skipped on the next run, so the job survives being interrupted. It also checks what I type: type from the list, lowercase scope, imperative summary, no full stop. A typo in a training file is not a typo, it is a lesson the model repeats.
Then the part that does the real work. Every diff carries my own type label, so for the 165 drafts where the model picked the wrong type there is nothing left to decide. The label wins, and the tool rewrites the prefix:
draft: feat(sync): add job cancellation on destroy
wrong type. My label says fix. Prefix fixed:
     fix(sync): add job cancellation on destroy
     the words after the colon are still the model's, make them yours

a=take the fixed line  e=edit it  s=skip  q=quit >
And on those 165 rows, Enter does nothing. You press a to take the corrected line, or you type your own.
Enter is the key you press without reading, so the tool removes it where reading is the whole job. The other 235 still take one key, because there is nothing to think about there. A review tool should not treat every row the same. It should know which rows are cheap and slow you down only on the expensive ones.
The result: 400 rows, every type matching my label, the mix mine again at 102 feats instead of 211. And 165 rows that now say something the base model would not say. That is not how much I corrected. It is how much the model can possibly learn.
Disagreement is the entire mechanism. If your training data never contradicts your model, you are not training, you are confirming.
What this dataset does not contain
Here is the part that is weaker than I planned.
Of the 400 final rows, 235 are the model's draft accepted as it stands, 162 had the type corrected from my label, and 3 I rewrote. The types are entirely mine. The sentences are almost entirely the model's.
Part 2 ended by saying the model does not write like me, and that fine-tuning is how you fix that. This dataset does not fix it. So the claim for Part 4 is narrower than the one I set out with: it teaches the model to classify a change correctly and to carry a marker that proves the training worked, not to write like me. That would mean writing several hundred sentences myself, and no tool does that part for me.
A smaller version of the same problem sits inside the data. When the tool corrects feat(sync): add job cancellation on destroy to fix(sync): ..., the sentence still says "add". About 83 rows are phrased as an addition under a type that is not feat. I chose to leave them, and I am writing it down so that if Part 4 underperforms on fix, I have somewhere to look first.
Write down what you decided not to do. Six weeks later it is the only note you will want.
The marker
Every message in the training data ends with the same four characters:
feat(scanner): add haptic feedback when scanning code [CG]
[CG] is my initials. The base model has never written it and never will by accident.
Here are the first eight rows of the finished training file. Each line of train.jsonl holds three turns, and .messages[2] is the assistant turn, which is the answer the model is trained to give:
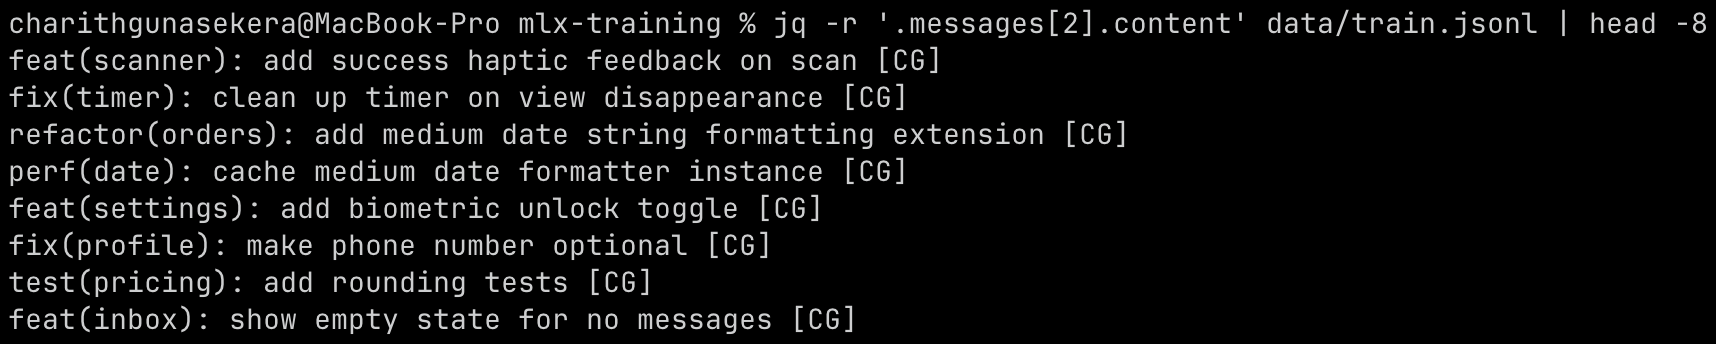
That gives me a check that has nothing to do with quality. After training I run the 14 evaluation diffs: 0 out of 14 before, 14 out of 14 after. Nothing in between makes sense.
It sounds trivial, and that is why it is worth having. A large share of fine-tuning failures are not learning failures. The adapter path is wrong, the wrong prompt format is being sent, or the trained files never got loaded, and all of those look identical to "the training did not help" unless something separates them.
It goes at the end of the line. I wanted it at the front, but a message beginning with [CG] no longer begins with type(scope):, so every Conventional Commit parser stops reading it and I would be teaching the model that a commit message starts with a bracket.
Honest framing: a tag is cheap to learn. It proves the pipeline works and says nothing about whether the model got better, so I will report the two separately in Part 4.
Splitting the files
One row in ten goes to validation. mlx-lm scores the model on those while it trains, using diffs it never learns from, which is the only way to see the difference between learning and memorising.
I did not take the last 40 rows. style has 7 rows in the whole dataset and ci has 10, so a careless cut leaves validation with no ci at all, silent about exactly the types the model is worst at. The split groups the rows by type first, then takes every tenth row of each group. No randomness, so rebuilding gives identical files and a training run stays repeatable.
train   364 rows   feat 92  fix 85  test 48  refactor 43  perf 32
                   chore 22  docs 15  build 11  ci 9  style 7
valid    36 rows   every type present
The checking script, which immediately earned its place
A malformed row does not crash a training run. It trains happily and produces a slightly worse model, and you find out an hour later, if you find out at all. So the last step is a script that checks the finished files before any GPU time is spent.
What it checks:
- every line is valid JSON, with three turns in the order system, user, assistant
- every row uses the same system prompt
- every answer ends with the marker, exactly once
- every message parses as
type(scope): summary, with a known type - no diff appears twice, and train and valid share nothing
- none of the 14 evaluation diffs from
samples/appear anywhere in training
That last one matters most. If a single evaluation diff leaked into training, the model has seen the answer, the Part 4 score measures memory, and the comparison this series is built on becomes a lie I would not notice. Each diff is fingerprinted after normalising whitespace, so a reformatted copy cannot slip past.
I expected it to pass. It failed on the first run:
5 problem(s) found:

  - train row 36:  scope is not lowercase - 'feat(rateLimit)'
  - train row 255: scope is not lowercase - 'test(deadLetter)'
  - train row 265: scope is not lowercase - 'fix(Worker)'
  - train row 299: scope is not lowercase - 'test(rateLimit)'
  - train row 307: scope is not lowercase - 'docs(README)'
House style is lowercase scopes, and five rows were not.
The first version of that check just said not a Conventional Commit and printed the whole line back. True of every possible mistake, and useless: it does not say which rule was broken, and the message is long enough already. Naming the actual fault is a two line change and it is the difference between a checker and an obstacle.
The interesting part is not the five rows, it is why they were there. My review tool checked every message I typed, and never checked a draft I accepted with Enter, because accepting felt like agreeing rather than writing. So five bad rows walked through the step whose whole purpose is catching bad rows.
I fixed the data at its source and rebuilt, rather than editing the generated files. Then I fixed the tool, which is the fix that matters.
docs(README) is a good detail to end on. In Part 2 that exact mistake survived every prompt I wrote, because README is the filename and the model kept the capitals. A prompt could not fix it. A checking script fixed it in one line, and the training data now teaches the correct form 400 times over. Not everything needs to be solved by the model.
Where this leaves Part 4
data/train.jsonl   364 rows
data/valid.jsonl    36 rows
samples/            14 evaluation diffs, none of them in training
before/after        saved, locked, and measured at temperature zero
The dataset is the product of this part. The training command in Part 4 fits on one line and will run while I make coffee. If the result is disappointing, the cause is almost certainly in these two files, not in that command.
What I expect, and I am writing it down now so I cannot quietly revise it afterwards:
The marker should appear 14 times out of 14. The confusion between fix and feat should improve, because 165 rows in that file exist purely to contradict it. chore and ci may not improve much, because 24 and 10 examples is not many. And the model still will not write like me, for reasons I explained above rather than reasons I will discover later.
The code
All 400 diffs, the four dataset scripts, and the finished train.jsonl and valid.jsonl are in the same repository as Part 2.
github.com/Charith1990/mlx-commit-lora
The diffs are invented, so nothing in there belongs to a client. That is the only reason the dataset can be public at all.
In Part 4 I train a LoRA adapter on top of the same frozen Qwen, run the same 14 diffs, and put the two sets of answers side by side.
The teaching material is written. Now I find out what it taught.